# Buck2 build system for Haskell projects
Short summary: this is a [cabal external command][ext] `cabal buck2`
that allows you to use [Buck2](https://buck2.build) as the build
system for your Cabal project.
# Quick start
First [download a buck2
binary](https://buck2.build/docs/getting_started/install/), unpack it
and put it on your `PATH`.
Then
```
cabal install cabal-buck2
```
Then in the root of your project or package:
```
git clone https://github.com/simonmar/haskell-buck2.git buck2 -b <version>
cabal buck2 --enable-tests
```
Where `<version>` is the version of `cabal-buck`,
e.g. `0.2.0.0`. Checking out the branch ensures that you get a
compatible copy of the Buck2 support code. `cabal buck2` checks that
`buck2/` is for its release (the `CABAL_BUCK2_VERSION` in
`buck2/version.bzl`), and so does buck2 when it reads the files that
`cabal buck2` generated, and the error says which branch to switch to.
Then you can use `buck2` as the build tool, e.g.
```
buck2 build //...
```
To build all the components, or
```
buck2 test //...
```
To run your tests.
Note that you need to re-run `cabal buck2 --enable-tests` if you
modify the `cabal.project` or any of the `.cabal` files.
Not all Cabal features are supported - see [limitations](#limitations).
# Why?
(skip this section if you know why you want buck2)
Why might you want to use `buck2` as the build system compared with
just using `cabal`? Well, first off let me be clear that you *still
need Cabal*, because the Buck2 support doesn't know how to solve
package dependencies or build them. So the workflow consists of first
running `cabal buck2` to solve and build the dependencies, but once you've
done that you can switch to `buck2` for building. The idea is that
`buck2` is a more pleasant experience because:
* It's [faster than Cabal, particularly for rebuilds](#performance).
* It supports different build modes out of the box: the default is to
build in `dev` mode (unoptimised with dynamic linking) but adding
`-m opt` gives you optimisation and static linking. Note that Cabal
doesn't have a purely dynamic build mode: it always uses `-dynamic-too`
for libraries, which has a significant built-time performance cost.
* The Buck2 build is extensible. If you have anything that needs to be
generated as part of your build, or any non-standard tooling, then
hooking that up using Buck2 is far easier than Cabal. Furthermore
Buck2 knows how to rebuild things correctly when either the build
system or the code generator components change.
* It works a lot better than Cabal when you have non-Haskell code (e.g. C/C++ or Rust) in your project, because
* Buck2 understands dependencies between C/C++ source files and header files (Cabal doesn't: [issue #4306](https://github.com/haskell/cabal/issues/4306)), so when you modify a C/C++ header the correct things are rebuilt.
* Buck2 builds C/C++ files in parallel, while Cabal doesn't ([issue #7127](https://github.com/haskell/cabal/issues/7127))
* You can use [remote execution and caching](https://buck2.build/docs/users/remote_execution/). There is built-in support for using a build cache, see [Sharing build results (a build cache)](#sharing-build-results-a-build-cache) below.
Finally, if you have an existing codebase using Buck2 then this is the
basis of something that could "buckify" Cabal packages to integrate
into your build system. It needs a bit of work to be suitable for that
use case, though: `cabal buck2` builds all the external dependencies
and installs them in the Cabal store, whereas to integrate with an
existing build system you would want to satisfy those external
dependencies from the build system itself.
# How complete is it?
I've used it to build a few large projects, in particular the Cabal
project itself which consists of about 16 packages and a few hundred
source files. It can also build [Glean](https://glean.software), which
has some complex build requirements including custom codegen, FFI &
hsc2hs.
There are a few [limitations](#limitations), however.
# What `cabal buck2` does
You can run `cabal buck2` in a project or a single Cabal package. It
does the following:
1. Solves the `build-depends` constraints of your package(s) and
builds all the dependencies, much like `cabal build all --only-dependencies`
would.
2. Generates some files, notably:
* `BUCK` and `BUCK.cabal.bzl` in each package, these are the Buck2
build targets
* `cabal-buck2/autogen` in each package, this is where we put the
files that Cabal autogenerates, such as `cabal_macros.h` and
`Paths_<pkg>.hs`.
* `third-party/haskell`: tells Buck2 about all the prebuilt package
dependencies, either in the Cabal store or in GHC's package
DB (unless you build the dependencies from source, see below). In here we also record the GHC version you're using, and the
paths to any tool dependencies.
A component that can't be built with buck2 (e.g. `build-type: Custom`)
is an error: `cabal buck2` lists them and aborts, unless you give the
`--keep-going` flag in which case it will translate everything it
can and warn about the missing components.
# Buck2 quick start
To build your code:
```
buck2 build //...
```
The `//...` is Buck2's syntax for "all targets recursively below the
current directory". You can also build specific target(s), for example
`buck2 build cabal-install:cabal` would build the `cabal` target in
the `cabal-install` package. For more details see [Target
Pattern](https://buck2.build/docs/concepts/target_pattern/) in the
Buck2 docs.
Next you can run your tests:
```
buck2 test //...
```
# Customising the build
`cabal buck2` will generate all the `BUCK` files if they don't exist,
but you can also write your own if you want (`cabal buck2` won't
overwrite them).
The `BUCK` file usually goes in the same directory as your source
files. The targets that `cabal buck2` produces go in the
`BUCK.cabal.bzl` file, and are generated by a call to
`generated_targets()` from the `BUCK` file. This call takes some
arguments that you can use to override or transform the generated
targets - take a look at the comments in the generated code to see
how.
You can also completely override the generated targets and write a
`BUCK` file with your own rules, while still making use of the
pre-built dependencies that `cabal buck2` produces. For example, the
`BUCK` file for a simple Haskell library might look something like
```
load("//buck2:haskell.bzl", "haskell_library")
haskell_library(
name = "my-package",
srcs = [
"Some/Module.hs",
],
packages = [
"unordered-containers",
],
visibility = ["PUBLIC"],
)
```
and the `BUCK` file for a test might look like
```
load("//buck2:haskell.bzl", "haskell_test")
haskell_test(
name = "my-test",
srcs = {
"Main.hs" : "my-test.hs",
},
deps = [
"//:my-package",
],
packages = [
"test-framework",
"test-framework-hunit",
"HUnit",
],
)
```
You can find docs on how to write `BUCK` files in the Buck2 docs, e.g. [haskell_library](https://buck2.build/docs/prelude/rules/haskell/haskell_library/).
# Build modes
The Buck2 build system has two build modes:
* `dev`: the default, builds everything with `-O0` and dynamic linking. This is intended to give you the quickest edit-compile-test turnaround.
* `opt`: enable `-O` and link statically. This takes longer but the code runs faster.
To build with `opt`, use `-m opt`, e.g.
```
buck2 build my-package:my-program -m opt
```
There are other build options that can be selected in a similar way, such as `-m prof` to enable profiling. See `constraints/BUCK` for details.
# Sharing build results (a build cache)
By default buck2 keeps nothing between runs of its daemon, nor between
checkouts: after `buck2 kill`, or in a new worktree, everything is built again.
A cache of build results fixes that. Buck2 can use any server that implements
the Bazel remote execution API's action cache and CAS, **only to look results
up and store them: nothing is run remotely**. For example
[bazel-remote](https://github.com/buchgr/bazel-remote):
```
bazel-remote --dir ~/.cache/buck2 --max_size 20 --grpc_address 127.0.0.1:9092 --http_address 127.0.0.1:8080
cabal buck2 --cache=grpc://127.0.0.1:9092
```
`--cache` adds a block to `.buckconfig` (between `# >>> cabal buck2: cache`
and `# <<< cabal buck2: cache <<<`; anything else in the file is left alone),
which later runs keep. `cabal buck2 --no-cache` removes it. **Run
`buck2 kill` after changing it**: buck2 reads the cache's address when its
daemon starts, and a daemon that was already running keeps the old settings.
Things to know:
* **The server has to be running.** When it isn't, buck2 retries connecting
for about 45 seconds on each build before carrying on without the cache.
Re-run `cabal buck2` with `--no-cache` to stop using the cache.
* The key of a cached result includes the command line, the environment and
the contents of the inputs. It includes the exact packages from the Cabal
store (their unit ids), a fingerprint of the GHC installation (its version,
platform, source commit and the interface hashes of its boot packages) and
a fingerprint of the C toolchain (the versions of the C compiler, `ld`, the
C library and `libstdc++`). It does **not** include other files that are
found on the system, such as headers and libraries that are not part of
those. That is fine on one machine; **sharing a cache between machines with
different system software is not safe yet**.
* Compiling and linking C/C++ code is cached, `pkg-config` queries are not.
* **buck2 only downloads what is needed.** A result that is found in the cache
is not downloaded until something needs its files: a local action that has
it as an input, `buck2 run` or `buck2 test`, or it is what you asked to
build. So most intermediate results (the compiled modules of a library
that was cached as a whole, say) are never fetched. `buck2 build -M none
//...` goes further and does not download what you asked for either, which
is a fast way to find out whether everything is already in the cache: the
summary line shows how many actions were cache hits.
# Building the dependencies with buck2
By default the dependencies of your packages are built by `cabal`, into its
store, and Buck2 uses them from there. With `--source-deps` Buck2 builds them
too:
```
cabal buck2 --source-deps
```
The source of each dependency is unpacked under `dist-newstyle/src` and the
package gets a `BUCK` and `BUCK.cabal.bzl` like those of your own packages.
Only the packages that come with GHC are used from its package database; the
build then doesn't depend on the Cabal store at all. Together with a
[build cache](#sharing-build-results-a-build-cache) that means a dependency is
built once, and then found in the cache by every other checkout, which is the
job the store does for `cabal`.
Things to know:
* If any dependency package isn't supported by `cabal buck2`,
`--source-deps` will fail. The most common cause of this is a
package that uses `build-type: Custom` (see
[Custom build type](#custom-build-type)). In case of failure you can
either fall back to not using `--source-deps` or use `--keep-going`
to continue without the unsupported dependencies.
* Running `cabal buck2` again without `--source-deps` goes back to the store,
and removes the packages that were unpacked for the previous run.
* The tools that dependencies need to preprocess sources (`alex` and `happy`)
are built by buck2 too, when the project needs them.
* The build plan can only have one version of each package, because a package
in a `.cabal` file is referred to by its name. `cabal buck2` stops and lists
the packages that need more than one.
# Performance
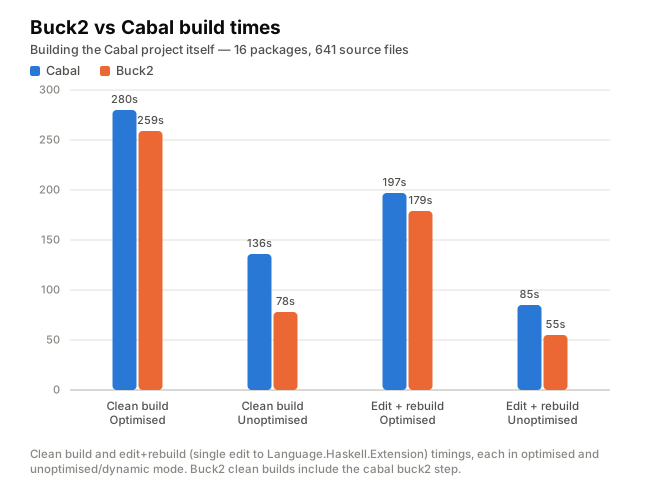
I ran some experiments building the Cabal project itself - 16 packages
and 641 source files (one package, `hackage-security`, is not part of
the project but has to be built locally nonetheless because it depends
on `Cabal-syntax` which *is* part of the project).
Buck2 shines when it comes to rebuilds: the dependency graph is cached
in memory, and it knows when build steps can be omitted because the
inputs haven't changed.
**Caveats**
* Results tend to be +/- a few seconds from run to run
* I didn't dig into the results in any detail
* It's just one set of data points. Different projects and different choices of edits could give different results. However, I did perform a similar
experiment with the [persistent](https://github.com/yesodweb/persistent)
project, and got similar results.
## Raw results and details
### Clean build
* Optimised:
* Default Cabal build: **280s**
* `cabal build all --enable-tests --enable-benchmarks -j`
* Buck2 build (opt mode, including `cabal buck2`): **259s**
* `cabal buck2 --enable-tests --enable-benchmarks && buck2 build //... -m opt`
* Not much difference here, as we expect.
* Unoptimised / dynamic:
* Cabal build with -O0 -dynamic: **136s**
* `cabal build all --enable-tests --enable-benchmarks -j --disable-optimisation --enable-executable-dynamic`
* Buck2 build (dev mode, including `cabal buck2`): **78s**
* `cabal buck2 --enable-tests --enable-benchmarks && buck2 build //... -m dev`
* Cabal is using `-dynamic-too` for libraries, while Buck2 is building everything purely dynamic.
### Edit + rebuild
Next I made a single edit (added an extension to
`Language.Haskell.Extension`) and rebuilt everything:
* Optimised:
* Cabal: **197s**
* Buck2: **179s**
* Unoptimised / dynamic:
* Cabal: **85s**
* Buck2: **55s**
# Limitations
## It's an external command, not builtin to `cabal-install`
This has some implications:
* `cabal` passes only the arguments after `buck2`, so global flags
given before it (`cabal --store-dir=... buck2`) don't reach the
tool. Use the environment (`CABAL_DIR`) instead.
* Nothing checks that your `cabal` binary matches the version of the
`cabal-install` library that `cabal-buck2` was built against. Try to
make sure they match, or confusion will undoubtedly ensue.
## Builds currently use `--make`
The current Buck2 prelude uses `ghc --make` to build each component
(library, executable). Ideally we should expose the full per-module
dependencies to Buck2 so that it can exploit parallelism across
packages for faster builds/rebuilds. It's entirely possible to do
this, indeed the functionality already exists in [Tweag's Haskell/Buck2
integration](https://github.com/tweag/buck2-haskell).
## Custom build type
Build-type `Custom` isn't supported, and can't be in general, so
`cabal buck2` will fail if any package requires it. Note that this
also applies to dependencies when `--source-deps` is being used. As
with other unsupported features, you can use `--keep-going` to just
skip all the affected packages.
## Hooks build type
There is partial support for `build-type: Hooks`: only configure hooks
are supported so far; files generated by pre-build rules are not.
The `SetupHooks` executable is built (by cabal) during `cabal buck2`,
including the package's `setup-depends`. It has to be built with the
same Cabal version as `cabal-buck2`, so `cabal-buck2` injects a
solver constraint to ensure that.
## **Template Haskell and `prof`**
A module that defines a splice must live in a *different*
`haskell_library()` from any module that uses it, when profiling (`-m
prof`). If not, the build will likely complain about a link error or a
missing object file at compile-time.
The situation with Template Haskell and profiling is complex, as is
the reason for this limitation.
* Without `-fexternal-interpreter`: GHC loads object code at
compile-time into its own process. Since GHC is itself a
dynamically-linked non-profiled executable, the objects it loads
must be shared, non-profiled, objects. So we have to build all the
dependencies of the current packages as shared libraries. This is
fine, except for the current package: GHC expects to find the
`.dyn_o` objects for the current package in the current `-odir`. But
Buck2 doesn't work this way: it builds the two instances of the
package separately. It's not clear if this is easily fixable.
* With `-fexternal-interpreter`, we could load the profiled non-shared
objects. However, this method uses the RTS runtime linker, which is
known to have some limitations and can't load some objects,
particularly on certain architectures. This is the main reason that
GHC switched to dynamic linking. So we don't go this route.
## No support for Cabal's `foreign-library`
Nothing fundamental blocking this, it's just a TODO.
## Preprocessors like `hspec-discover`
The `hspec-discover` preprocessor is designed to be invoked by GHC via
the `-pgmF` flag to specify a custom preprocessor. The problem is that
`hspec-discover` searches the filesystem to find other source files;
these other source files amount to implicit inputs to the compilation,
but when using Buck2 all inputs must be explicit (this is so that
compilation steps can be executed remotely).
To build an `hspec-discover` test with Buck2, you have to run the
preprocessor using a `genrule()` that takes all the source files as an
input. For example, if your test is in `test/Spec.hs`:
```
filegroup(
name = "srcs",
srcs = glob(["**/*.hs"])
)
genrule(
name = 'spec-gen',
cmd = "$(location third-party-haskell//:hspec-discover-exe) $(location :srcs)/test/Spec.hs test/Spec.hs ${OUT}",
out = "test/Spec.hs"
)
haskell_test(
name = 'spec',
srcs = {
'Main.hs': ':spec-gen',
...
},
...
)
```
# Acknowledgments
Most of the code and modifications to the standard Buck2 prelude were
developed with the help of Claude Code using Claude Sonnet 5/5.5.
The Haskell support already in the Buck2 prelude was developed by Meta
and is in production use internally for building
[Glean](https://glean.software). This project just fixes a few things
and adds some functionality needed to support building Cabal projects.
# Related projects
[Tweag](https://tweag.io) also worked on a [Haskell integration for
Buck2](https://www.youtube.com/watch?v=bbFnrTAIK9Q). This project has
no code in common with theirs, except for the shared upstream prelude
code. Tweag's integration is more sophisticated and was aimed at using
Buck2's improved scalability to build large Haskell projects.
[ext]: https://cabal.readthedocs.io/en/stable/external-commands.html